Encryption keeps a message secret but doesn’t stop an attacker from changing the message.
A cipher running in counter mode can turn a flipped ciphertext bit into a flipped plaintext bit at the same position. An adversary who cannot read a message can thus still change it, and the recipient will decrypt something that was never sent. Changes to encrypted content might result in parts of a message being decrypted into garbage but a receiver may not be able to tell when the data isn’t text, such as binary code or a stream of sensor data from a device.
Sometimes, there’s no need to keep a message secret but anyone receiving it should be confident that it has not been modified.
A software publisher can let anyone download an update, but a computer installing it needs to know that the copy has not been altered. Encryption does not solve the problem. The contents can be public while still needing protection against changes.
Encryption helps implement the “C” in the CIA Triad: confidentiality. It does nothing to address the “I”: integrity.
Integrity ensures that data has not been modified. Authenticity verifies that data came from the source it claims. A receiver usually needs both: an unchanged message from the expected sender.
Integrity Before Computers
A wax seal connected a document to a person or institution through a recognizable stamp. Opening a letter would leave visible damage to the wax. A seal placed directly on a document served a different purpose: authenticating the document without keeping it hidden. In either case, trust depended on who controlled the stamp and how the seal was attached. A wax seal on a document did not actually prevent an attacker from adding to the content, just like signing a contract does not guarantee that the other side will not be able to add to it.
Committing to a Discovery Without Revealing It
Seventeenth-century scientists faced a problem: establishing priority for a discovery before they were ready to reveal it. Publishing the details gave rivals an opportunity to claim the work, while keeping everything secret left no public record of the discovery (proving you were first). What was needed was a way to fix a claim in public, at a known date, while keeping its content hidden until the author was ready to defend it.
The solution they came up with was using an anagram. The author wrote a brief summary of the discovery as a sentence, scrambled its letters, often by sorting them into alphabetical order, and published the resulting string. Later, when the work was ready, the author revealed the sentence. Anyone could check that its letters matched what had been published.
In 1610, Galileo Galilei published this string:
smaismrmilmepoetaleumibunenugttauirasHe revealed it as Altissimum planetam tergeminum observavi, “I have observed the highest planet to be triple-formed.” He was looking at Saturn through a telescope that could not resolve its rings, so he saw what looked like a body with an attachment on each side. Later that year, he published a second anagram of his observation that Venus shows phases as the Moon does. Christiaan Huygens later took the same approach to claim priority for his observations of the rings of Saturn.
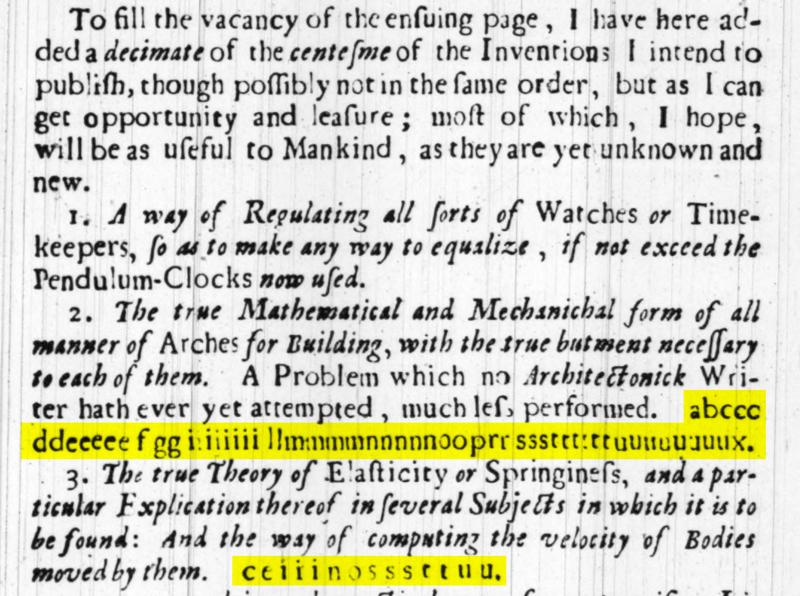
In A Description of Helioscopes (1676), Robert Hooke concealed his theory of elasticity in the string ceiiinosssttuu.1 He disclosed the solution two years later as: Ut tensio, sic vis, or “as the extension, so the force.” This was Hooke’s Law, which defines the relationship between how far a spring is stretched and the force it exerts. He published two additional anagrams in the same book (you can see all three on pages 31-32).
What the Anagram Was Doing
These anagrams served as a form of a commitment scheme, which is a cryptographic technique that allows one to commit to some data with the ability to reveal it later.
A commitment scheme needs two properties.
-
It has to hide.
The published string must reveal nothing about the message behind it. Sorted letters accomplished this, since a reader has no practical way to reconstruct the Latin sentence. -
It has to bind.
Once the string is published, the author must not be able to claim a different statement later. Binding is where the anagram fails. The published string scrambles a short summary of a longer message. Binding holds only if nobody can find a second message that produces the same summary. A set of letters is a weak summary, because many different sentences can be built from the same one.
A public procedure that reduces a long message to a short summary is a hash function. Anagrams didn’t accomplish that. The rest of this section is about building one whose binding holds.
Telegraph Checks and Accidental Errors
As telegraph networks expanded in the nineteenth century, companies made extensive use of codebooks. Sending text by cable was expensive, so businesses replaced common phrases, quantities, and instructions with short code words, often five letters long, drawn from published books. This compression created a new problem: a letter garbled in transmission could sometimes turn one valid code word into another with a completely different meaning, potentially changing a price, quantity, or shipping instruction.
The compilers of these books built defenses into them. Books such as Liebèr’s Five Letter American Telegraphic Code created fixed published lists of codes, and the better lists were chosen so that any two words differed in at least two letters. The 1920 edition of the ABC Telegraphic Code was built on that rule. A single garbled letter therefore could not turn one valid code word into another.
The same idea entered computing.
-
A check digit is an extra digit appended to an account or product number and computed from the rest of it. Credit cards use these, for example.
-
A parity bit appended to a byte records whether the number of one bits is even or odd. This is common in memory chips to detect single-bit errors.
-
A cyclic redundancy check (CRC) computes a remainder over the entire message, and is present in Ethernet frames, disk blocks, and ZIP files. IPv4 uses a simpler checksum over the header alone, while the TCP and UDP checksums cover the data as well.
All of these were designed to protect against accidental corruption. Their simple mathematical structure lets an attacker construct deliberate changes that preserve the check. Detecting hostile edits requires a calculation designed to resist someone who knows how it works.
Cryptographic Hash Functions
For protecting data such as software downloads, a useful check value is one that an attacker cannot preserve while changing the data. The check also needs to stay small enough to store or transmit conveniently, even for gigabytes of data.
A cryptographic hash function maps a message to a fixed-size value called a hash or digest. SHA-256, one of the Secure Hash Algorithms, produces 256 bits whether the message contains just a few words or is a multi-gigabyte software package (32 bytes, usually written as 64 hexadecimal characters).
We write the operation as \(h = H(m)\): hash the message \(m\) to obtain the digest \(h\). No secret key is involved, so anyone with the message can calculate its digest.
Two messages that differ in a single word produce unrelated digests. For example, these two inputs use uppercase letters and single spaces, with no trailing newline:
SEND TEN CRATES
5cfa7ec86e3054bc9a03bfb5a77de7478bd8660f2fa073dc2944f2261df1e14f

SEND TWO CRATES
247c7640e6071c0a35f9408003d6717cb348e28d57ac5e711f0bc8091a137dfe
Changing TEN to TWO leaves the size of the message unchanged and changes 122 of the 256 digest bits, roughly half. A change that a word count would have missed has spread throughout the digest.
A change as minor as a period to the message also changes the resulting hash dramatically, changing 125 bits in this case:
SEND TEN CRATES.
431e56effedd6f80ee55469b1af1801fd9f5024bc70401db30a0871d7032457e
You can test this yourself on a Linux system with the command:
echo -n "SEND TEN CRATES" | openssl sha256Properties of a Cryptographic Hash
A cryptographic hash function combines predictable behavior for its users with resistance to deliberate manipulation. The function is public and takes no key, so anyone can compute a digest, and everyone who computes it over the same input gets the same result.
Seven properties describe the requirements for a cryptographic hash function:
- Fixed-length output.
- The digest is the same size no matter how long the message is. This is what makes a digest cheap to store, publish, or sign. As we’ll see, it is also the reason collisions must exist.
- Determinism.
- The same input always produces the same digest. Without this, a digest could not verify anything.
- Preimage resistance.
- The function works in one direction only. Given a digest \(h\), it is infeasible to find any message \(m\) with \(H(m) = h\), and the digest does not expose the length or the contents of the message it came from. Concealment depends on the message being unpredictable. If the set of possible messages is small, an attacker can hash every candidate and compare the results, so hashing a yes-or-no answer conceals nothing.
- Second preimage resistance.
- Given a message \(m_1\), it is infeasible to find a different message \(m_2\) with \(H(m_2) = H(m_1)\). This prevents an attacker from replacing a published software update with a modified file that passes the original hash check. This is the property the anagram lacked.
- Collision resistance.
- It is infeasible to find any pair of different messages \(m_1\) and \(m_2\) with \(H(m_1) = H(m_2)\).
- Avalanche.
- Similar messages produce very different-looking digests. A small change to the input (even just one bit) changes about half the bits of the digest, and the set of bits changed is unpredictable. Two digests reveal nothing about how similar their inputs were.
- Efficiency.
- Computing the digest should be fast, with work roughly proportional to the message’s size. Checking a large software package must be efficient enough to do whenever it is downloaded or installed.
Second preimage resistance and collision resistance protect against different people:
-
Second preimage resistance protects a document that already exists from an outsider who wants to substitute another one for it.
-
Collision resistance protects against the author of the document, who could prepare two versions in advance, have one approved, and present the other.
Collision resistance is the stronger requirement, since the attacker gets to choose both messages.
Why Collisions Exist
Collisions must exist because there are more possible messages than fixed-size digests.
The pigeonhole principle says that if there are more items than containers, at least one container holds more than one item. A hash function maps inputs of every length onto a fixed number of digests, so there are far more possible inputs than outputs (an infinite number, theoretically), so some inputs must share the same output. The requirement for a hash function is not that collisions do not exist, but that finding a colliding pair takes an infeasible amount of work.
Searching for a second preimage means finding a message that hashes to one specific digest, which takes about \(2^n\) attempts for an \(n\)-bit digest.
Searching for any collision at all is a different problem, because each new message can be compared against every message already tried. The number of pairs grows as the square of the number of messages, so a collision turns up after roughly \(2^{n/2}\) attempts.
The birthday problem illustrates why. Among 23 people, the probability that any two share a birthday is greater than 50%, although there are 365 possible birthdays. It feels counterintuitive because the search is not for someone with a specific birthday but rather for any two people who share the same birthday.
The consequence for design is that a digest must be twice as long as the collision resistance required of it. An ideal 128-bit hash provides about 64 bits of collision resistance, meaning that a generic collision attack requires roughly \(2^{64}\) hash computations. This is still an enormous amount of work. To obtain 128 bits of collision resistance, a hash needs a 256-bit digest. MD5 is substantially weaker than the ideal case because attacks exploit flaws in its design. This is why 256 bits is the floor for new systems. The doubling applies only to collisions. Finding a preimage for a digest of \(n\) bits still costs about \(2^{n}\).
A weakness in a particular hash function can bring the cost below even that. Attacks of that kind have broken the collision resistance of older hash functions, such as MD5 and SHA-1. In 2017, researchers at Google and CWI, a Dutch mathematics and computer science research institute, published two different PDF files with the same SHA-1 digest. They constructed both files for the attack. Replacing an arbitrary existing file with one that has the same digest would require a second-preimage attack, which this result did not provide.
Note that the amount of comutation required to create those two files that produced the same hash was not trivial, but feasible. According to Google’s report, it took:
-
Nine quintillion (9,223,372,036,854,775,808) SHA1 computations in total
-
6,500 years of CPU computation to complete the attack first phase
-
110 years of GPU computation to complete the second phase.
That’s a lot of computation, but it was 100,000 times less work than a brute force attack would have taken.
How a Hash Function Is Built
A designer faces the problem that the input has no fixed length. The usual approach, used by MD5, SHA-1, and the SHA-2 family of hash functions, is to build a small function that mixes one fixed-size block of the message into a running value, and then to apply it to each block of the message in turn. The message is padded so that it divides evenly into blocks. The running value starts at a fixed constant, every block updates it. The value after processing the last block is the digest.
   start -----> mix -----> mix -----> mix -----> digest
                 ^          ^          ^
              block 1    block 2    block 3
SHA-256 belongs to SHA-2, a family with several digest lengths (SHA-256 refers to the 256-bit version; SHA-512 to the 512-bit version). SHA-3 is a separately designed family, standardized in 2015. Both are recommended by the U.S. National Institute of Standards and Technology (NIST), the federal agency that develops and publishes U.S. cryptographic standards.
What Hash Functions Are Used For
Hash functions appear throughout systems software, and the uses fall into a few groups:
-
Verifying a transfer. A publisher lists the digest of a file, and whoever downloads it recomputes the digest and compares it with the original.
-
Naming content. Git identifies every commit, file, and directory by the digest of its contents, so any change produces a different name and cannot pass unnoticed. IPFS and BitTorrent name content the same way.
-
Committing to data. Publishing a digest now and the data later is similar to the old anagram technique, done correctly. Trusted timestamping services and the certificate logs we will cover later both work this way.
-
Storing passwords. Systems should store password hashes rather than passwords, using deliberately expensive hashing to slow guessing. We will cover password storage later.
-
Linking records. Each block in a blockchain contains the digest of the block before it, so altering an old block invalidates every block after it. We will cover this in detail later.
-
Finding duplicates. Backup and storage systems compare digests to avoid storing the same data twice.
A Digest Needs a Trusted Reference
A software publisher distributes a file and publishes its expected digest. The receiver hashes the downloaded file and compares the result with the published value. A mismatch exposes corruption or substitution. A match is useful only if the receiver can trust the published digest.
An attacker who controls the download page can replace the file and publish a new digest for the replacement. The receiver’s calculation still matches. SHA-256 did not fail, but the attacker updated the hash to that of the file that is being checked. Obtaining the expected digest independently, through a channel the attacker does not control, would expose the substitution (this is what bittorrent does, where the hashes sit in torrent files while blocks of data are downloaded from arbitrary servers). The same holds for a digest that travels alongside the data it describes, over the same connection.
Anyone can calculate a hash, so hashing alone cannot establish who supplied a file. The receiver needs a check that depends on something the legitimate sender controls and the attacker does not.
Next: Part 2: Authenticating Messages with Shared Secrets
-
Latin of this period did not distinguish u from v, and Hooke’s printer set both as u. Sorting the letters of ut tensio, sic vis in a modern alphabet ends in u and v, so some sources show the anagram as
ceiiinosssttuv. ↩